| Authors: | Brent Motmans, Digvijay Ghogare, Thijs G.I. van Wijk, Joren Van Herck, Saba Heidarian, Pieter De Meyer, Berend Smit, An Hardy, and Danny E. P. Vanpoucke |
| Journal: | Chem. Mater XX, YYY (2026) |
| doi: | ZZ |
| IF(2025): | 7.1 |
| export: | bibtex |
| pdf: | <ChemMater_XX> <ArXiv> |
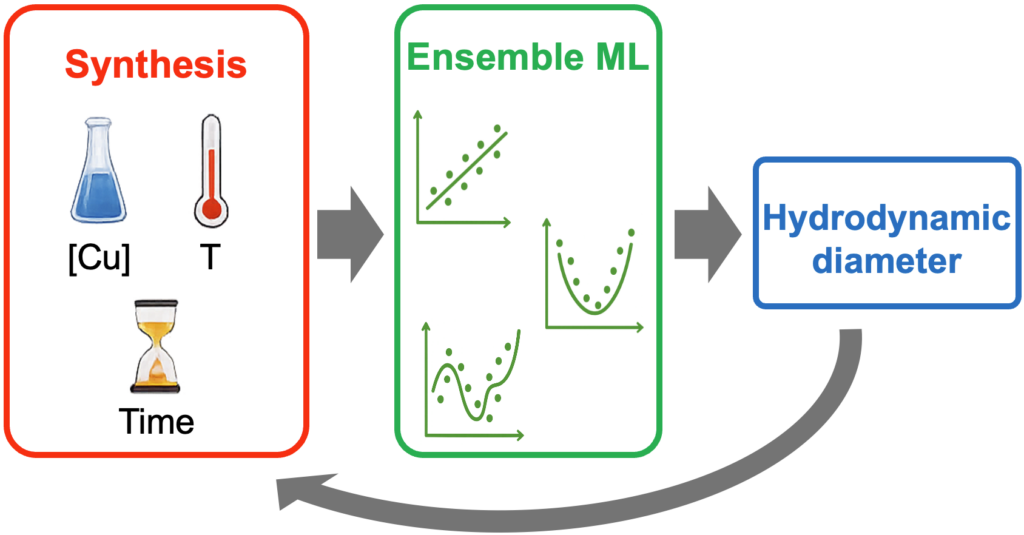 |
| Graphical Abstract: A machine learning approach to predict the hydrodynamic diameter of Cu Nanoparticles using a small data approach. |
Abstract
Copper nanoparticles (Cu NPs) have a broad applicability, yet their synthesis is sensitive to subtle changes in reaction parameters. This sensitivity, combined with the time- and resource-intensive nature of experimental optimization, poses a major challenge in achieving reproducible and size-controlled synthesis. While Machine Learning (ML) shows promise in materials research, its application is often limited by scarcity of large high-quality experimental data sets. This study explores ML to predict the DLS-derived hydrodynamic diameter of Cu NPs from microwave-assisted polyol synthesis using a small data set of 25 in-house performed syntheses. Latin Hypercube Sampling is used to efficiently cover the parameter space while creating the experimental data set. Ensemble regression models successfully predict hydrodynamic diameters with good predictive performance given the limited dataset. Since quantitative regression requires a unique DLS-derived hydrodynamic diameter, the regression model is restricted to mono-modal DLS distributions, while a complementary classification model identifies synthesis conditions for which quantitative prediction is applicable. Using equivalent out-of-sample validation (OOB and LOOCV), the ML and DoE models showed comparable generalization (MAE -= 40.92 and 40.46 nm, respectively). The final ensemble model achieved an R2 of 0.74, an MAE of 23.81 nm, compared to an R2 of 0.60, an MAE of 33.54 nm for the DoE model, while retaining the complete synthesis parameter space, making it better suited for synthesis guidance. Additionally, classification models using both random forests and Large Language Models (LLMs) are evaluated to distinguish between large and small particles. These classification models exhibited only modest predictive performance, indicating that this small dataset is insufficient to fully exploit the capabilities of complex LLMs. Overall, this study demonstrates that carefully curated small data sets, paired with robust classical ML, can effectively support the synthesis of Cu NPs and highlights that for lab-scale studies, complex models like LLMs may offer limited benefits. The validation experiments further indicate the potential of ML guided synthesis to improve the efficiency of experimental optimization and reduce resource consumption.