Category: blog

Exa-scale computing future in Europe?

As a computational materials scientist with a main research interest in the ab initio simulation of materials, computational resources are the life-blood of my research. Over the last decade, I have seen my resource usage grow from less than 100.000 CPU hours per year to several million CPU-hours per year. To satisfy this need for computational resources I have to make use of HPC facilities, like the TIER-2 machines available at the Flemish universities and the Flemish TIER-1 supercomputer, currently hosted at KU Leuven. At the international level, computational scientists have access to so called TIER-0 machines, something I no doubt will make use of in the future. Before I continue, let me first explain a little what this TIER-X business actually means.

The TIER-X notation is used to give an indication of the size of the computer/supercomputer indicated. There are 4 sizes:

  •  TIER-3: This is your personal computer(laptop/desktop) or even a small local cluster of a research group. It can contain from one (desktop) up to a few hundred CPU’s (local cluster). Within materials research, this is sufficient for quite a few tasks: post-processing of data, simple force-field based calculations, or even small quantum chemical or solid state calculations. A large fraction of the work during my first Ph.D. was performed on the local cluster of the CMS.
  • TIER-2: This is a supercomputer hosted by an institute or university. It generally contains over 1000 CPUs and has a peak performance of >10 TFLOPS (1012 Floating Point Operations Per Second, compare this to 1-50×109 FLOPS or 1-25 GFLOPS of an average personal computer). The TIER-2 facilities of the VUB and UAntwerp both have a peak performance of about 75TFLOPS , while the machines at Ghent University and the KU Leuven/Uhasselt facilities both have a peak performance of about 230 TFLOPS. Using these machines I was able to perform the calculations necessary for my study of dopant elements in cerates (and obtain my second Ph.D.).
  • TIER-1: Moving up one more step, there are the national/regional supercomputers. These generally contain over 10.000 CPUs and have a peak performance of over 100 TFLOPS. In Flanders the Flemish Supercomputer Center (VSC) manages the TIER-1 machine (which is being funded by the 5 Flemish universities). The first TIER-1 machine was hosted at Ghent University, while the second and current one is hosted at KU Leuven, an has a peak performance of 623 TFLOPS (more than all TIER-2 machines combined), and cost about 5.5 Million € (one of the reasons it is a regional machine). Over the last 5 years, I was granted over 10 Million hours of CPU time, sufficient for my study of Metal-Organic Frameworks and defects in diamond.
  • TIER-0: This are international level supercomputers. These machines contain over 100.000 CPUs, and have a peak performance in excess of 1 PFLOP (1 PetaFLOP = 1000 TFLOPS). In Europe the TIER-0 facilities are available to researchers via the PRACE network (access to 7 TIER-0 machines, accumulated 43.49 PFLOPS).

This is roughly the status of what is available today for Flemish scientists at various levels. With the constantly growing demand for more processing power, the European union, in name of EuroHPC, has decided in march of this year, that Europe will host two Exa-scale computers. These machines will have a peak performance of at least 1 EFLOPS, or 1000 PFLOPS. These machines are expected to be build by 2024-2025. In June, Belgium signed up to EuroHPC as the eighth country participating, in addition, to the initial 7 countries (Germany, France, Spain, Portugal, Italy, Luxemburg and The Netherlands).

This is very good news for all involved in computational research in Flanders. There is the plan to build these machines, there is a deadline, …there just isn’t an idea of what these machines should look like (except: they will be big, massively power consuming and have a target peak performance). To get an idea what users expect of such a machine, Tier-1 and HPC users have been asked to put forward requests/suggestions of what they want.

From my user personal experience, and extrapolating from my own usage I see myself easily using 20 million hours of CPU time each year by the time these Exa-scale machines are build. Leading a computational group would multiply this value. And then we are talking about simple production purpose calculations for “standard” problems.

The claim that an Exa-scale scale machine runs 1000x faster than a peta-scale machine, is not entirely justified, at least not for the software I am generally encountering. As software seldom scales linearly, the speed-gain from Exa-scale machinery mainly comes from the ability to perform many more calculations in parallel. (There are some exceptions which will gain within the single job area, but this type of jobs is limited.) Within my own field, quantum mechanical calculation of the electronic structure of periodic atomic systems, the all required resources tend to grow with growth of the problem size. As such, a larger system (=more atoms) requires more CPU-time, but also more memory. This means that compute nodes with many cores are welcome and desired, but these cores need the associated memory. Doubling the cores would require the memory on a node to be doubled as well. Communication between the nodes should be fast as well, as this will be the main limiting factor on the scaling performance. If all this is implemented well, then the time to solution of a project (not a single calculation) will improve significantly with access to Exa-scale resources. The factor will not be 100x from a Pflops system, but could be much better than 10x. This factor 10 also takes into account that projects will have access to much more demanding calculations as a default (Hybrid functional structure optimization instead of simple density functional theory structure optimization, which is ~1000x cheaper for plane wave methods but is less accurate).

At this scale, parallelism is very important, and implementing this into a program is far from a trivial task. As most physicists/mathematicians/chemists/engineers may have the skills for writing scientifically sound software, we are not computer-scientists and our available time and skills are limited in this regard. For this reason, it will become more important for the HPC-facility to provide parallelization of software as a service. I.e. have a group of highly skilled computer scientists available to assist or even perform this task.

Next to having the best implementation of software available, it should also be possible to get access to these machines. This should not be limited to a happy few through a peer review process which just wastes human research potential. Instead access to these should be a mix of guaranteed access and peer review.

  • Guaranteed access: For standard production projects (5-25 million CPU hours/year) university researchers should have a guaranteed access model. This would allow them to perform state of the are research without too much overhead. To prevent access to people without the proven necessary need/skills it could be implemented that a user-database is created and appended upon each application. Upon first application, a local HPC-team (country/region/university Tier-1 infrastructure) would have to provide a recommendation with regard to the user, including a statement of the applicant’s resource usage at that facility. Getting resources in a guaranteed access project would also require a limited project proposal (max 2 pages, including user credentials, requested resources, and small description of the project)
  • Peer review access: This would be for special projects, in which the researcher requires a huge chunk of resources to perform highly specialized calculations or large High-throughput exercises (order of 250-1000 million CPU hours, e.g. Nature Communications 8, 15959 (2017)). In this case a full project with serious peer review (including rebuttal stage, or the possibility to resubmit after considering the indicated problems). The goal of this peer review system should not be to limit the number of accepted projects, but to make sure the accepted projects run successfully.
  • Pay per use: This should be the option for industrial/commercial users.

What could an HPC user as myself do to contribute to the success of EuroHPC? This is rather simple, run the machine as a pilot user (I have experience on most of the TIER-2 clusters of Ghent University and both Flemish Tier-1 machines. I successfully crashed the programs I am using by pushing them beyond their limits during pilot testing, and ran into rather unfortunate issues. 🙂 That is the job of a pilot user, use the machine/software in unexpected ways, such that this can be resolved/fixed by the time the bulk of the users get access.) and perform peer review of the lager specialized projects.

Now the only thing left to do is wait. Wait for the Exa-scale supercomputers to be build…7 years to go…about 92 node-days on Breniac…a starting grant…one long weekend of calculations.

Appendix

For simplicity I use the term CPU to indicate a single compute core, even though technically, nowadays a single CPU will contain multiple cores (desktop/laptop: 2-8 cores, HPC-compute node: 2-20 cores / CPU (or more) ). This to make comparison a bit more easy.

Furthermore, modern computer systems start more and more to rely on GPU performance as well, which is also a possible road toward Exa-scale computing.

Orders of magnitude:

  • G = Giga = 109
  • T = Tera = 1012
  • P = Peta = 1015
  • E = Exa = 1018

Permanent link to this article: https://dannyvanpoucke.be/exa-scale-computing/

Just married

Today is a joyful day, as I am getting married to my lovely girlfriend, my partner in crime, the mother of our son, the stars of my night-sky: my wife.

In February, we silently snuck out and got married (just the two of us and our son). We even had a small honeymoon/pilgrimage to Enschede, the place where it all began. We visited the town and the university campus, reliving old memories of those first days.

Today, we have the ring-ceremony and wedding party to share our happiness  with our family and friends. As we are having the celebration at a local castle, Sylvia also designed a special coat of arms for our little family:


Calculemus et Sapiamus

Permanent link to this article: https://dannyvanpoucke.be/just-married/

Resource management on HPC infrastructures.

Computational as a third pillar of science (next to experimental and theoretical) is steadily developing in many fields of science. Even some fields you would less expect it, such as sociology or psychology. In other fields such as physics, chemistry or biology it is much more widespread, with people pushing the boundaries of what is possible. Larger facilities provide access to larger problems to tackle. If a computational physicist is asked if larger infrastructures would not become too big, he’ll just shrug and reply: “Don’t worry, we will easily fill it up, even a machine 1000x larger than that.” An example is given by a pair of physicists who recently published their atomic scale study of the HIV-1 virus. Their simulation of a model containing more than 64 million atoms used force fields, making the simulation orders of magnitude cheaper than quantum mechanical calculations. Despite this enormous speedup, their simulation of 1.2 µs out of the life of an HIV-1 virus (actually it was only the outer skin of the virus, the inside was left empty) still took about 150 days on 3880 nodes of 16 cores on the Titan super computer of Oak Ridge National Laboratory (think about 25 512 years on your own computer).

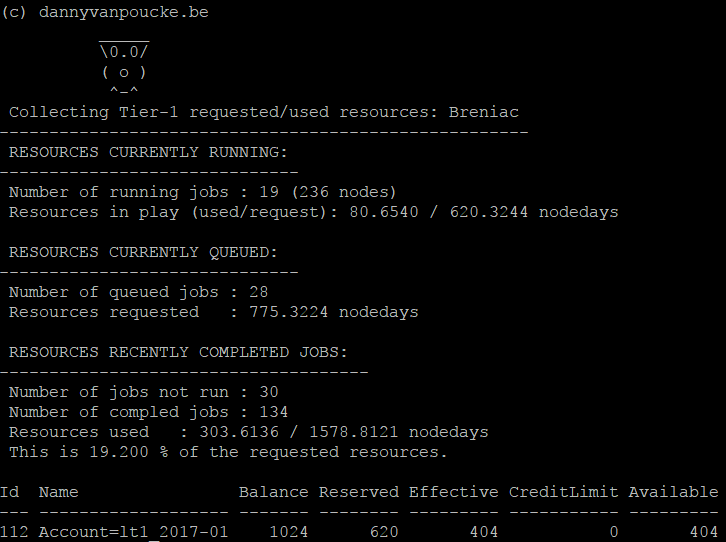
In Flanders, scientist can make use of the TIER-1 facilities provided by the Flemish Super Computer (VSC). The first Tier-1 machine was installed and hosted at Ghent University. At the end of it’s life cycle the new Tier-1 machine (Breniac) was installed and is hosted at KULeuven. Although our Tier-1 supercomputer is rather modest compared to the Oak Ridge supercomputer (The HIV-1 calculation I mentioned earlier would require 1.5 years of full time calculations on the entire machine!) it allows Flemish scientists (including myself) to do things which are not possible on personal desktops or local clusters. I have been lucky, as all my applications for calculation time were successful (granting me between 1.5 and 2.5 million hours of CPU time every year). With the installment of the new supercomputer accounting of the requested resources has become fully integrated and automated. Several commands are available which provide accounting information, of which mam-balance is the most important one, as it tells how much credits are still available. However, if you are running many calculations you may want to know how many resources you are actually asking and using in real-time. For this reason, I wrote a small bash-script that collects the number of requested and used resources for running jobs:

[codesyntax lang="bash" lines="normal" blockstate="collapsed"]
#small script to collect TIER-1 usage and requested resources
#!/bin/bash
echo "(c) dannyvanpoucke.be"
echo "          _____"
echo "          \0.0/"
echo "          ( o )"
echo "           ^-^ "
echo " Collecting Tier-1 requested/used resources: Breniac "
echo "-----------------------------------------------------"

#step one running resources
RCRrt="0"
RCRwt="0"
tnodes="0"
numl=`qstat -n | grep " R " | wc -l`
for (( i=1 ; i<= $numl ; i++ )); do
lin=`qstat -n | grep " R " | head -$i | tail -1`
nodes=`echo $lin | awk '{print $6}'`
tnodes=$( echo "$tnodes + $nodes" | bc )
lin=`echo $lin | sed 's/:/\ /g'`
rth=`echo $lin | awk '{print $13}'`
rtm=`echo $lin | awk '{print $14}'`
rts=`echo $lin | awk '{print $15}'`
wth=`echo $lin | awk '{print $9}'`
wtm=`echo $lin | awk '{print $10}'`
wts=`echo $lin | awk '{print $11}'`

rtuse=$( bc -l << EOF
scale=4
$nodes * (($rth + ( $rtm + ( $rts / 60.0000 ) )/60.0000)/24.00)
EOF
)
wtuse=$( bc -l << EOF
scale=4
$nodes * (($wth + ( $wtm + ( $wts / 60.0000 ) )/60.0000)/24.00)
EOF
)
RCRrt=$( bc -l << EOF
scale=4
$RCRrt + $rtuse
EOF
)
RCRwt=$( bc -l << EOF
scale=4
$RCRwt + $wtuse
EOF
)
done

echo " RESOURCES CURRENTLY RUNNING:"
echo "------------------------------"
echo " Number of running jobs : "$numl" ($tnodes nodes)"
echo " Resources in play (used/request): $RCRrt / $RCRwt nodedays"
echo " "
#step two queued resources

RCQwt="0"
numl=`qstat -n | grep " Q " | wc -l`
for (( i=1 ; i<= $numl ; i++ )); do
lin=`qstat -n | grep " Q " | head -$i | tail -1`
nodes=`echo $lin | awk '{print $6}'`
lin=`echo $lin | sed 's/:/\ /g'`
wth=`echo $lin | awk '{print $9}'`
wtm=`echo $lin | awk '{print $10}'`
wts=`echo $lin | awk '{print $11}'`

wtuse=$( bc -l << EOF
scale=4
$nodes * (($wth + ( $wtm + ( $wts / 60.0000 ) )/60.0000)/24.00)
EOF
)

RCQwt=$( bc -l << EOF
scale=4
$RCQwt + $wtuse
EOF
)
done

echo " RESOURCES CURRENTLY QUEUED:"
echo "------------------------------"
echo " Number of queued jobs : "$numl
echo " Resources requested   : $RCQwt nodedays"
echo " "

#step three used resources in ended jobs
cnt="0"
RCFrt="0"
RCFwt="0"
numl=`qstat | grep " C " | wc -l`
#mam-statement does give the ID's but no further info can be extracted from qstat.
#numl=`mam-statement | grep $project | grep 'UsageRecord' | wc -l`
# list of jobIDs
LST=`qstat | grep " C " | sed 's/\./\ /g' | awk '{print $1}'`
#LST=`mam-statement | grep $project | grep 'UsageRecord' | awk '{print $3}'`

for jobid in `echo $LST`; do
#check if the job actually ran
tst=`qstat -f $jobid | grep 'walltime' | wc -l`
if [ "$tst" == "2" ]; then
nodes=`qstat -f $jobid | grep nodect | awk '{print $3}'`
lin=`qstat -f $jobid | grep 'resources_used.walltime' | awk '{print $3}' | sed 's/:/\ /g'`
rth=`echo $lin | awk '{print $1}'`
rtm=`echo $lin | awk '{print $2}'`
rts=`echo $lin | awk '{print $3}'`
lin=`qstat -f $jobid | grep 'Resource_List.walltime' | awk '{print $3}' | sed 's/:/\ /g'`
wth=`echo $lin | awk '{print $1}'`
wtm=`echo $lin | awk '{print $2}'`
wts=`echo $lin | awk '{print $3}'`

rtuse=$( bc -l << EOF
scale=4
$nodes * (($rth + ( $rtm + ( $rts / 60.0000 ) )/60.0000)/24.00)
EOF
)
wtuse=$( bc -l << EOF
scale=4
$nodes * (($wth + ( $wtm + ( $wts / 60.0000 ) )/60.0000)/24.00)
EOF
)

RCFrt=$( bc -l << EOF
scale=4
$RCFrt + $rtuse
EOF
)
RCFwt=$( bc -l << EOF
scale=4
$RCFwt + $wtuse
EOF
)

else
# if the job didn't run
cnt=$(bc -l << EOF
scale=0
$cnt + 1
EOF
)
fi
done

pct=$( bc -l << EOF
scale=3
 ( $RCFrt / $RCFwt ) * 100.00
EOF
)

#remove the number of not-run jobs
numl=$(bc -l << EOF
scale=0
$numl - $cnt
EOF
)

echo " RESOURCES RECENTLY COMPLETED JOBS:"
echo "-------------------------------------"
echo " Number of jobs not run : "$cnt
echo " Number of compled jobs : "$numl
echo " Resources used   : $RCFrt / $RCFwt nodedays"
echo " This is "$pct" % of the requested resources."
echo " "

# finish with the Balance
mam-balance
[/codesyntax]

Output of the Bash Script.

Currently, the last part, on the completed jobs, only provides data based on the most recent jobs. Apparently the full qstat information of older jobs is erased. However, it still provides an educated guess of what you will be using for the still queued jobs.


Permanent link to this article: https://dannyvanpoucke.be/pbsbalancecollector-en/

Functional Molecular Modelling: simulating particles in excel

This semester I had several teaching assignments. I was a TA for the course biophysics for the first bachelor biomedical sciences, supervised two 3rd bachelor students physics during their first steps in the realm of computational materials science, and finally, I was responsible for half the course Functional Molecular Modelling for the first Masters Biomedical students (Bioelectronics and Nanotechnology). In this course, I introduce the the students into the basic concepts of classical molecular modelling (quantum modelling is covered by Prof. Wilfried Langenaeker). It starts with a reiteration of some basic concepts from statistics and moves on to cover the canonical ensemble. Things get more interesting with the introduction into Monte-Carlo(MC) and Molecular Dynamics(MD), where I hope to teach the students the basics needed to perform their own MC and MD simulations. This also touches the heart of what this course should cover. If I hear a title like Functional Molecular Modelling, my thoughts move directly to practical applications, developing and implementing models, and performing simulations. This becomes a bit difficult as none of the students have any programming experience or skills.

Luckily there is excel. As the basic algorithms for MC and MD are actually quite simple, this office package can be (ab)used to allow the students to perform very simple simulations. This even without the use of macro’s or any advanced features. Because Excel can also plot the data present in the cells, you immediately see how properties of the simulated system vary during the simulation, and you get direct update of all graphs every time a simulation is run.

It seems I am not the only one who is using excel for MD simulations. In 1995, Fraser and Woodcock even published a paper detailing the use of excel for performing MD simulations on a system of 100 particles. Their MD is a bit more advanced than the setup I used as it made heavy use of macro’s and needed some features to speed things up as much as possible. With the x486 66MHz computers available at that time, the simulations took of the order of hours. Which was impressive, as they served as an example of how computational speed had improved over the years, and compared to the months of supercomputer resources one of the authors had needed 25 years earlier to perform the same thing for his PhD. Nowadays the same excel simulation should only take minutes, while an actual program in Fortran or C may even execute the same thing in a matter of seconds or less.

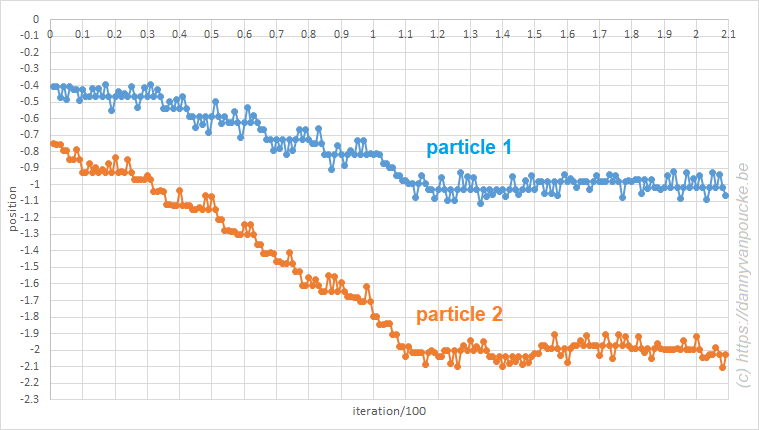
For the classes and exercises, I made use of a simple 3-atom toy-model with Lennard-Jones interactions. The resulting simulations remain clear allowing their use for educational purposes. In case of  MC simulations, a nice added bonus is the fact that excel updates all its fields automatically when a cell is modified. As a result, all random numbers are regenerated and a new simulation can be performed by saving the excel-sheet or just modifying a not-used cell.

Monte Carlo in excel. A system of three particles on a line, with one particle fixed at 0. All particles interact through a Lennard-Jones potential. The Monte Carlo simulation shows how the particles move toward their equilibrium position.

Monte Carlo in excel. A system of three particles on a line, with one particle fixed at 0. All particles interact through a Lennard-Jones potential. The Monte Carlo simulation shows how the particles move toward their equilibrium position.

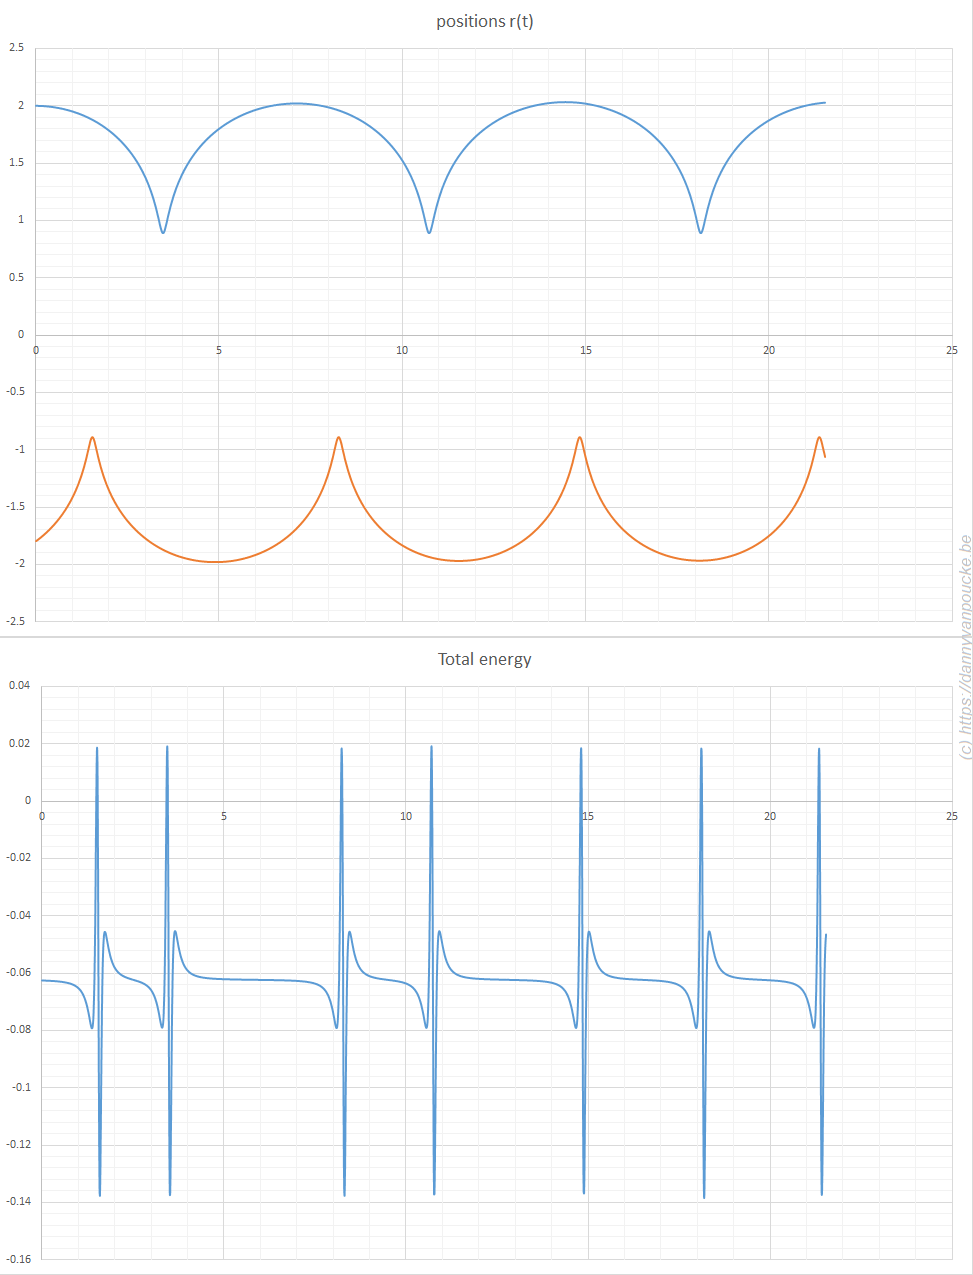
The simplicity of Newton’s equations of motion make it possible to perform simple MD simulations, and already for a three particle system, you can see how unstable the algorithm is. Implementation of the leap-frog algorithm isn’t much more complex and shows incredible the stability of this algorithm. In the plot of the total energy you can even see how the algorithm fights back to retain stability (the spikes may seem large, but the same setup with a straight forward implementation of Newton’s equation of motion quickly moves to energies of the order of 100).

Molecular dynamics in excel. A system of three particles on a line, with one particle fixed at 0. All particles interact through a Lennard-Jones potential. The Molecular dynamics simulation shows how the particles move as time evolves. Their positions are updated using the leap-frog algorithm. The extreme hard nature of the Lennard-Jones potential gives rise to the sharp spikes in the total energy. It is this last aspect which causes the straight forward implementation of Newton's equations of motion to fail.

Molecular dynamics in excel. A system of three particles on a line, with one particle fixed at 0. All particles interact through a Lennard-Jones potential. The Molecular dynamics simulation shows how the particles move as time evolves. Their positions are updated using the leap-frog algorithm. The extreme hard nature of the Lennard-Jones potential gives rise to the sharp spikes in the total energy. It is this last aspect which causes the straight forward implementation of Newton’s equations of motion to fail.


Permanent link to this article: https://dannyvanpoucke.be/functional-molecular-modelling-simulating-particles-in-excel/

Bachelor Projects Completed: 2 new computational materials scientists initialised

The black arts of computational materials science.

Black arts of computational materials science.

Just over half a year ago, I mentioned that I presented two computational materials science related projects for the third bachelor physics students at the UHasselt. Both projects ended up being chosen by a bachelor student, so I had the pleasure of guiding two eager young minds in their first steps into the world of computational materials science. They worked very hard, cursed their machine or code (as any good computational scientist should do once in a while, just to make sure that he/she is still at the forefront of science) and survived. They actually did quite a bit more than “just surviving”, they grew as scientists and they grew in self-confidence…given time I believe they may even thrive within this field of research.

One week ago, they presented their results in a final presentation for their classmates and supervisors. The self-confidence of Giel, and the clarity of his story was impressive. Giel has a knack for storytelling in (a true Pan Narrans as Terry Pratchett would praise him). His report included an introduction to various topics of solid state physics and computational materials science in which you never notice how complicated the topic actually is. He just takes you along for the ride, and the story unfolds in a very natural fashion. This shows how well he understands what he is writing about.

This, in no way means his project was simple or easy. Quite soon, at the start of his project Giel actually ran into a previously unknown VASP bug. He had to play with spin-configurations of defects and of course bumped into a hand full of rookie mistakes which he only made once *thumbs-up*. (I could have warned him for them, but I believe people learn more if they bump their heads themselves. This project provided the perfect opportunity to do so in a safe environment. 😎 )  His end report was impressive and his results on the Ge-defect in diamond are of very good quality.

The second project was brought to a successful completion by Asja. This very eager student actually had to learn how to program in fortran before he could even start. He had to implement code to calculate partial phonon densities with the existing HIVE code. Along the way he also discovered some minor bugs (Thank you very much 🙂  ) and crashed into a rather unexpected hard one near the end of the project. For some time, things looked very bleak indeed: the partial density of equivalent atoms was different, and the sum of all partial densities did not sum to the total density. As a result there grew some doubts if it would be possible to even fulfill the goal of the project. Luckily, Asja never gave up and stayed positive, and after half a day of debugging on my part the culprit was found (in my part of the code as well). Fixing this he quickly started torturing his own laptop calculating partial phonon densities of state for Metal-organic frameworks and later-on also the Ge-defect in diamond, with data provided by Giel. Also these results are very promising and will require some further digging, but they will definitely be very interesting.

For me, it has been an interesting experience, and I count myself lucky with these two brave and very committed students. I wish them all the best of luck for the future, and maybe we meet again.

Permanent link to this article: https://dannyvanpoucke.be/bachelor-projects-completed/

VSC-user day 2017: The Poster Edition

Last Friday, the HPC infrastructure in Flanders got celebrated by the VSC user day. Being one of the Tier-1 supercomputer users at UHasselt, I was asked if I could present a poster at the meeting, showcasing the things I do here. Although I was very interested in this event, educational obligations (the presentations of the bachelor projects, on which I will post later) prevented me from attending the meeting.

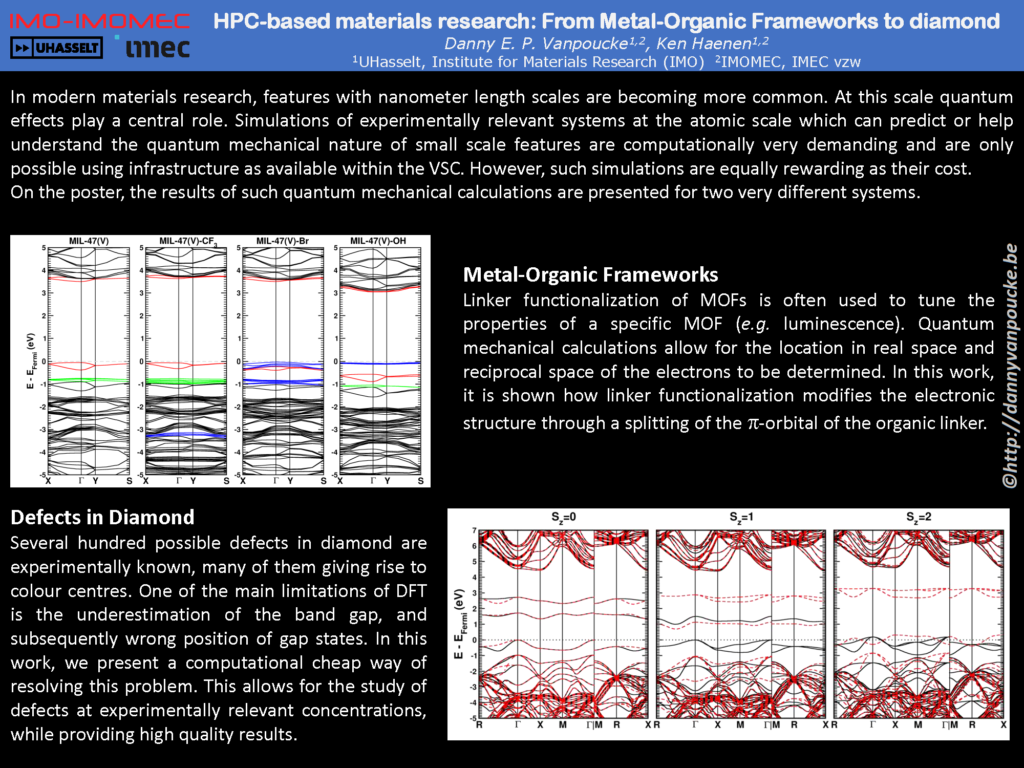
As means of a compromise, I created a poster for the meeting which Geert Jan Bex, our local VSC/HPC support team, would be so nice to put up at the event. The poster session was preceded by a set of 1-minute presentations of the posters, for which a slide had to be made. As I could not be physically present, I provided the organizers a slide which contained a short description that could be used as the 1-minute presentation. Unfortunately, things got a little mixed up, as Geert Jan accidentally printed this slide as the poster (which gave rise to some difficulties in the printing process 🙄 ). So for those who might have had an interest in the actual poster, let me put it up here:

This poster presents my work on linker functionalisation of the MIL-47, which got recently published in the Journal of physical chemistry C, and the diamond work on the C-vacancy, which is currently submitted. Clicking on the poster above will provide you the full size image. The 1-minute slide presentation, which erroneously got printed as poster:

Permanent link to this article: https://dannyvanpoucke.be/vsc-user-day-2017-the-poster-edition/

improved security: “https”

With a recent transfer of this website to a new server, I was able to move it more or less entirely into the HTTPS domain. The main reason for doing this is the recent hobby of Google (and chrome as it’s extension) to target HTTP websites to indicate them as insecure [1,2,3]. The transfer from HTTP to HTTPS provides some security with regard to Man-In-The-middle attacks (or for those with the background in quantum information and quantum cryptography: it protects Alice and Bob from Eve…). It unfortunately will not protect my website from being hacked, nor you if I would include “evil” scripts into a page or post. 😈

Those who are interested in the “security” of this website may notice some pages are not yet labeled as secure. The origin lies in the sitemeter used to measure traffic. As it does not allow for an HTTPS connection to the used script. Other than that everything on the pages should be over HTTPS. The sole exceptions are some of the posts, which may still be using the HTTP version of the CSS style sheets and javascript scripts used to securely hide my email. If you notice something like this, feel free to put it in a comment under the post, and I’ll fix it as soon as possible.).


Permanent link to this article: https://dannyvanpoucke.be/improved-security-https/

Revisiting the Neutral C-vacancy in Diamond

For a recent project, attempting to investigate Eu dopants in bulk diamond, I ended up simplifying the problem and investigating the C-vacancy in diamond. The setup is simple: take a super cell of diamond, remove 1 carbon atom and calculate. This, however, ended up being a bit more complicated than I had expected.

Removing the single carbon atom gives rise to 4 dangling bonds on the neighboring carbon atoms. The electrons occupying these bonds will gladly interact with one another, giving rise to three different possible spin states:

  1. All spins oriented the same (Ferromagnetic configuration: ↑↑↑↑ or 4x½ ⇒ Sz=2 spin state)
  2. Three spins in the same direction and one in the opposite direction ( ↑↑↑↓ or (3x½)-½ ⇒ Sz=1 spin state)
  3. Two spins up, and two spins down (↑↑↓↓ or (2x½)-(2x½) ⇒Sz=0 spin state)

Starting the calculations without any assumptions gives nice results. Unfortunately they are wrong, and we seem to have ended up in nearby local minima. Including the spin-configurations above as starting assumptions solves the problem, luckily.

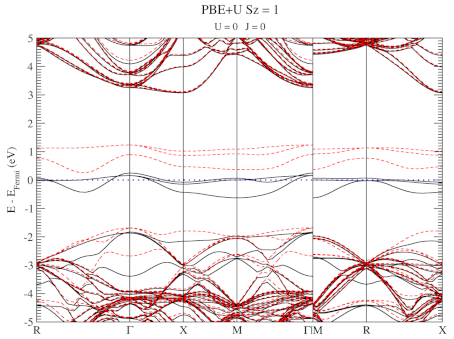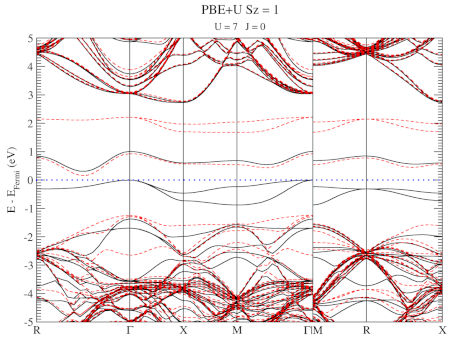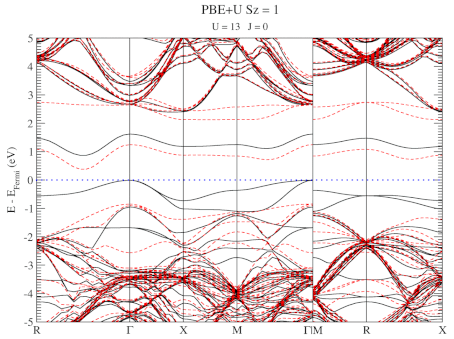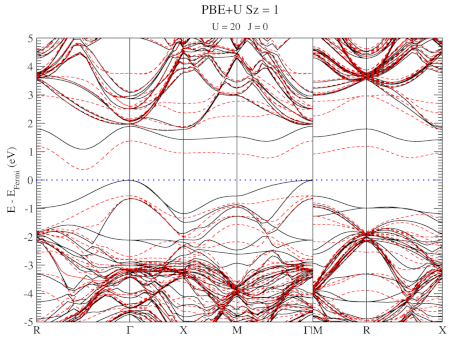
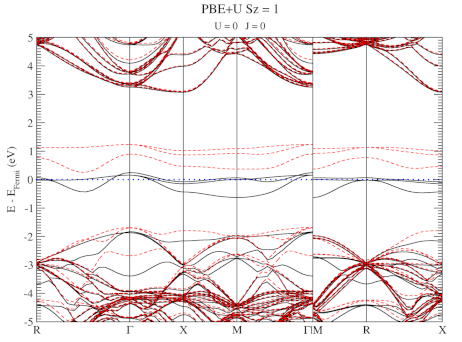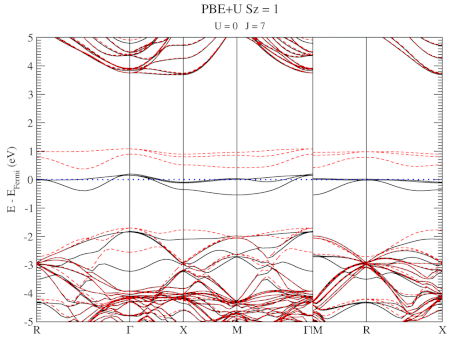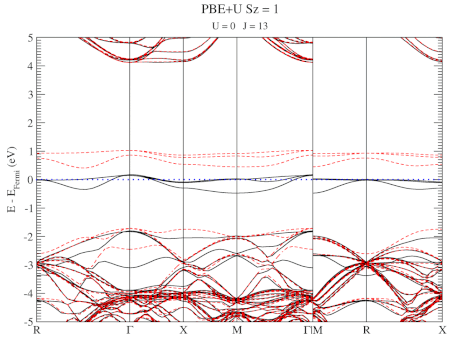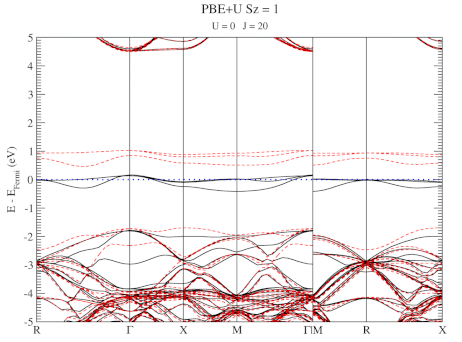
The electronic structure is, however, still not a perfect match for experiment. But this is well-known behavior for Density Functional Theory with local functionals such as LDA and PBE. A solution is the use of hybrid functionals (such as HSE06). Conservation of misery kicks in hard at this point, since the latter type of calculations are 1000x as expensive in compute time (and the LDA and PBE calculations aren’t finished in a matter of seconds or minutes, but need several hours on multiple cores). An old methodology to circumvent this problem is the use of Hubbard-U like correction terms (so-called DFT+U). Interestingly for this defect system the two available parameters in a DFT+U setup are independent, and allow for the electronic structure to be perfectly tuned. At the end of the fitting exercise, we now have two additional parameters, which allow us to get electronic structures of hybrid functional quality, but at PBE computational cost.

The evolution of the band-structure as function of the two parameters can be seen below.

DFT+U series (varying U) for a specific spin state of the C-vacancy defect.

DFT+U series (varying U) for a specific spin state of the C-vacancy defect.

DFT+U series (varying J) for a specific spin state of the C-vacancy defect.

DFT+U series (varying J) for a specific spin state of the C-vacancy defect.

Permanent link to this article: https://dannyvanpoucke.be/diamond-dftu-en/

VASP tutor: Structure optimization through Equation-of-State fitting

Materials properties, such as the electronic structure, depend on the atomic structure of a material. For this reason it is important to optimize the atomic structure of the material you are investigating. Generally you want your system to be in the global ground state, which, for some systems, can be very hard to find. This can be due to large barriers between different conformers, making it easy to get stuck in a local minimum. However, a very shallow energy surface will be problematic as well, since optimization algorithms can get stuck wandering these plains forever, hopping between different local minima (Metal-Organic Frameworks (MOFs) and other porous materials like Covalent-Organic Frameworks and Zeolites are nice examples).

VASP, as well as other ab initio software, provides multiple settings and possibilities to perform structure optimization. Let’s give a small overview, which I also present in my general VASP introductory tutorial, in order of increasing workload on the user:

  1. Experimental Structure: This the most lazy option, as it entails just taking an experimentally obtained structure and not optimizing it at all. This should be avoided unless you have a very specific reason why you want to use specifically this geometry. (In this regard, Force-Field optimized structures fall into the same category.)
  2. Simple VASP Optimization: You can let VASP do the heavy lifting. There are several parameters which help with this task.
    1. IBRION = 1 (RMM-DIIS, good close to a minimum), 2 (conjugate gradient, safe for difficult problems, should always work), 3 (damped molecular dynamics, useful if you start from a bad initial guess) The IBRION tag determines how ions are moved during relaxation.
    2. ISIF = 2 (Ions only, fixed shape and volume), 4 (Ions and cell shape, fixed volume), 3 (ions, shape and volume relaxed) The ISIF tag determines how the stress tensor is calculated, and which degrees of freedom can change during a relaxation.
    3. ENCUT = max(ENMAX)x1.3  To reduce Pulay stresses, it is advised to increase the basis set to 1.3x the default value, which is the largest ENMAX value for the atoms used in your system.
  1. Volume Scan (Quick and dirty): For many systems, especially simple systems, the internal coordinates of the ions are often well represented in available structure files. The main parameter which needs optimization is the lattice parameter. This is also often the main change if different functional are used. In a quick and dirty volume scan, one performs a set of static calculations, only the volume of the cell is changed. The shape of the cell and the internal atom coordinates are kept fixed. Fitting a polynomial to the resulting Energy-Volume data can then be used to obtain the optimum volume. This option is mainly useful as an initial guess and should either be followed by option 2, or improved to option 4.
  2. Equation of state fitting to fixed volume optimized structures: This approach is the most accurate (and expensive) method. Because you make use of fixed volume optimizations (ISIF = 4), the errors due to Pulay stresses are removed. They are still present for each separate fixed volume calculation, but the equation of state fit will average out the basis-set incompleteness, as long as you take a large enough volume range: 5-10%. Note that the 5-10% volume range is generally true for small systems. In case of porous materials, like MOFs, ±4% can cover a large volume range of over 100 Å3. Below you can see a pseudo-code algorithm for this setup. Note that the relaxation part is split up in several consecutive relaxations. This is done to further reduce basis-set incompleteness errors. Although the cell volume does not change, the shape does, and the original sphere of G-vectors is transformed into an ellipse. At each restart this is corrected to again give a sphere of G-vectors. For many systems the effect may be very small, but this is not always the case, and it can be recognized as jumps in the energy going from one relaxation calculation to the next. The convergence is set the usual way for a relaxation in VASP (EDIFF and EDIFFG parameters) and a threshold in the number of ionic steps should be set as well (5-10 for normal systems is reasonable, while for porous/flexible materials you may prefer a higher value). There exist several possible equations-of-state which can be used for the fit of the E(V) data. The EOSfit option of HIVE-4 implements 3:
    1. Birch-Murnaghan third order isothermal equation of state
    2. Murnaghan equation of state
    3. Rose-Vinet equation of state (very well suited for (flexible) MOFs)

    Using the obtained equilibrium volume a final round of fixed volume relaxations should be done to get the fully optimized structure.

[codesyntax lang=”c” title=”Pseudo-code”]

For (set of Volumes: equilibrium volume ±5%){
	Step 1          : Fixed Volume relaxation
	(IBRION = 2, ISIF=4, ENCUT = 1.3x ENMAX, LCHARG=.TRUE., NSW=100)
	Step 2→n-1: Second and following fixed Volume relaxation (until a threshold is crossed and the structure is relaxed in fewer than N ionic steps) (IBRION = 2, ISIF=4, ENCUT = 1.3x ENMAX, ICHARG=1, LCHARG=.TRUE., NSW=100) 
	Step n : Static calculation (IBRION = -1, no ISIF parameter, ICHARG=1, ENCUT = 1.3x ENMAX, ICHARG=1, LCHARG=.TRUE., NSW=0) 
} 
Fit Volume-Energy to Equation of State.
Fixed volume relaxation at equilibrium volume. (With continuations if too many ionic steps are required.) 
Static calculation at equilibrium volume

[/codesyntax]

EOS-fitting Diamond and Graphite

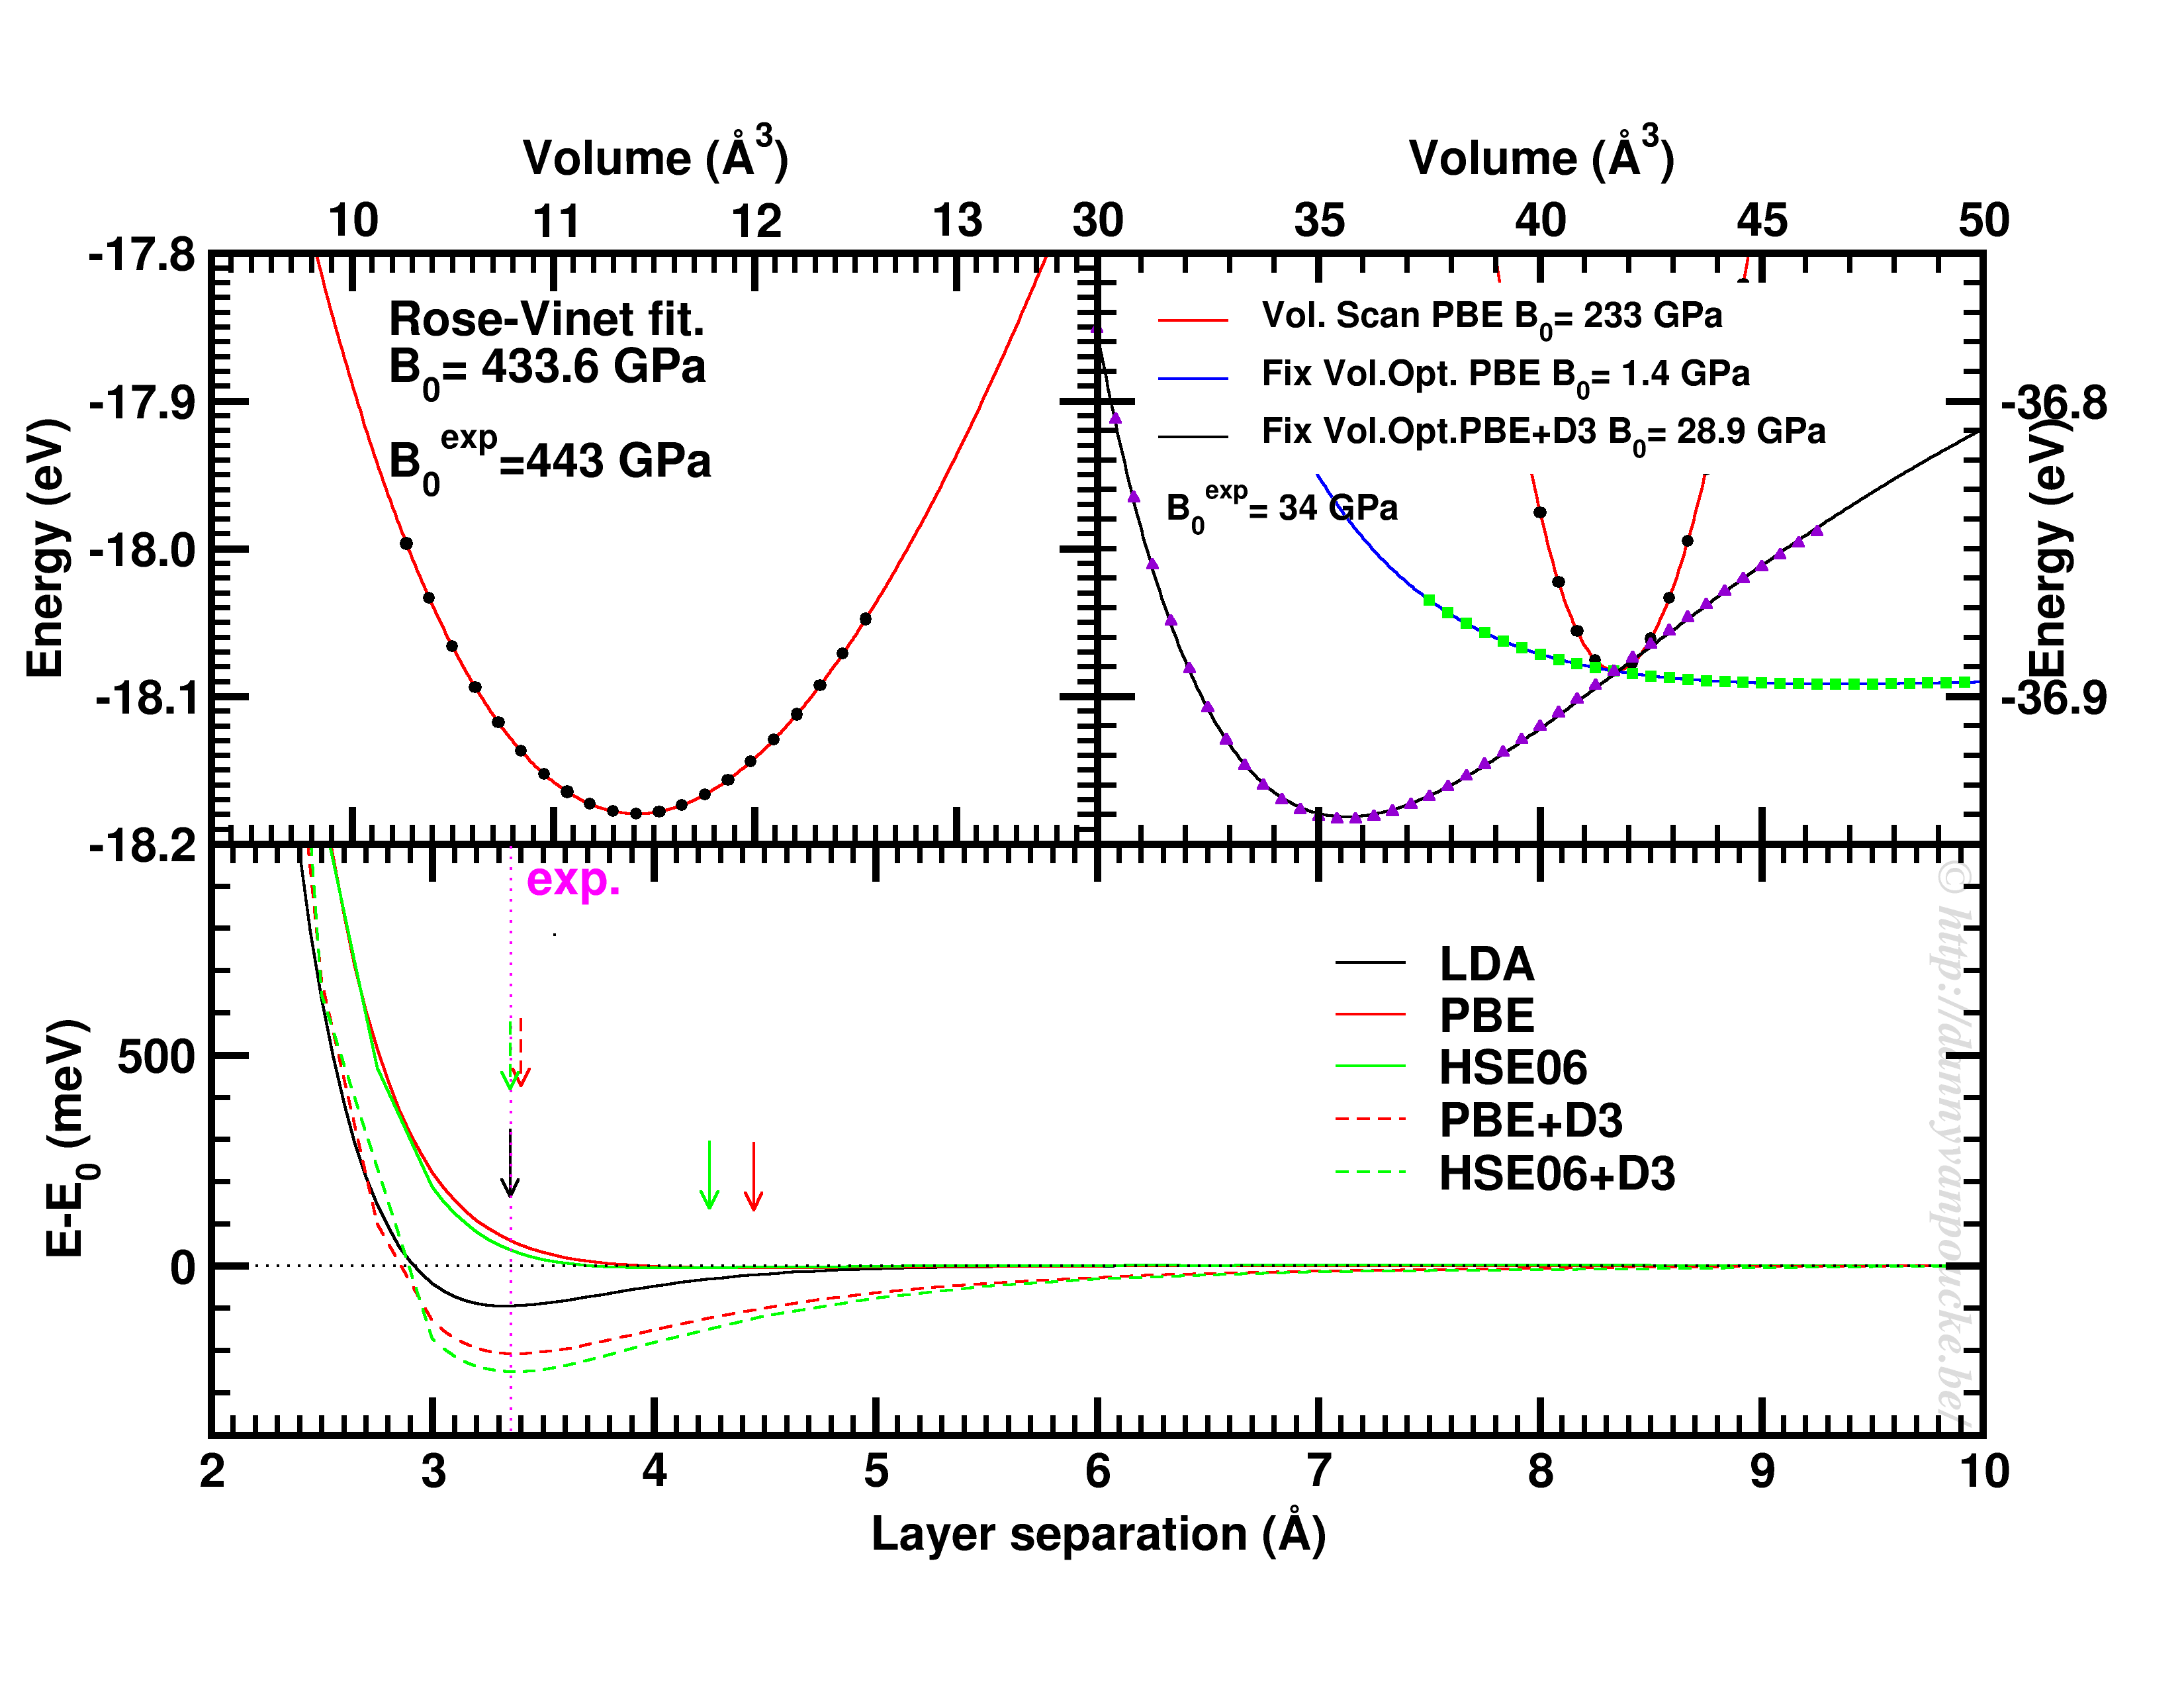
Top-left: Volume scan of Diamond. Top-right: comparison of volume scan and equation of state fitting to fixed volume optimizations, showing the role of van der Waals interactions. Bottom: Inter-layer binding in graphite for different functionals.

Some examples

Let us start with a simple and well behaved system: Diamond. This material has a very simple internal structure. As a result, the internal coordinates should not be expected to change with reasonable volume variations. As such, a simple volume scan (option 3), will allow for a good estimate of the equilibrium volume. The obtained bulk modulus is off by about 2% which is very good.

Switching to graphite, makes things a lot more interesting. A simple volume scan gives an equilibrium volume which is a serious overestimation of the experimental volume (which is about 35 Å3), mainly due to the overestimation of the c-axis. The bulk modulus is calculated to be 233 GPa a factor 7 too large. Allowing the structure to relax at fixed volume changes the picture dramatically. The bulk modulus drops by 2 orders of magnitude (now it is about 24x too small) and the equilibrium volume becomes even larger. We are facing a serious problem for this system. The origin lies in the van der Waals interactions. These weak forces are not included in standard DFT, as a result, the distance between the graphene sheets in graphite is gravely overestimated. Luckily several schemes exist to include these van der Waals forces, the Grimme D3 corrections are one of them. Including these the correct behavior of graphite can be predicted using an equation of state fit to fixed volume optimizations.(Note that the energy curve was shifted upward to make the data-point at 41 Å3 coincide with that of the other calculations.) In this case the equilibrium volume is correctly estimated to be about 35 Å3 and the bulk modulus is 28.9 GPa, a mere 15% off from the experimental one, which is near perfect compared to the standard DFT values we had before.

In case of graphite, the simple volume scan approach can also be used for something else. As this approach is well suited to check the behaviour of 1 single internal parameter, we use it to investigate the inter-layer interaction. Keeping the a and b lattice vectors fixed, the c-lattice vector is scanned. Interestingly the LDA functional, which is known to overbind, finds the experimental lattice spacing, while both PBE and HSE06 overestimate it significantly. Introducing D3 corrections for these functionals fixes the problem, and give a stronger binding than LDA.

EOS-fitting for MIL53-MOFs

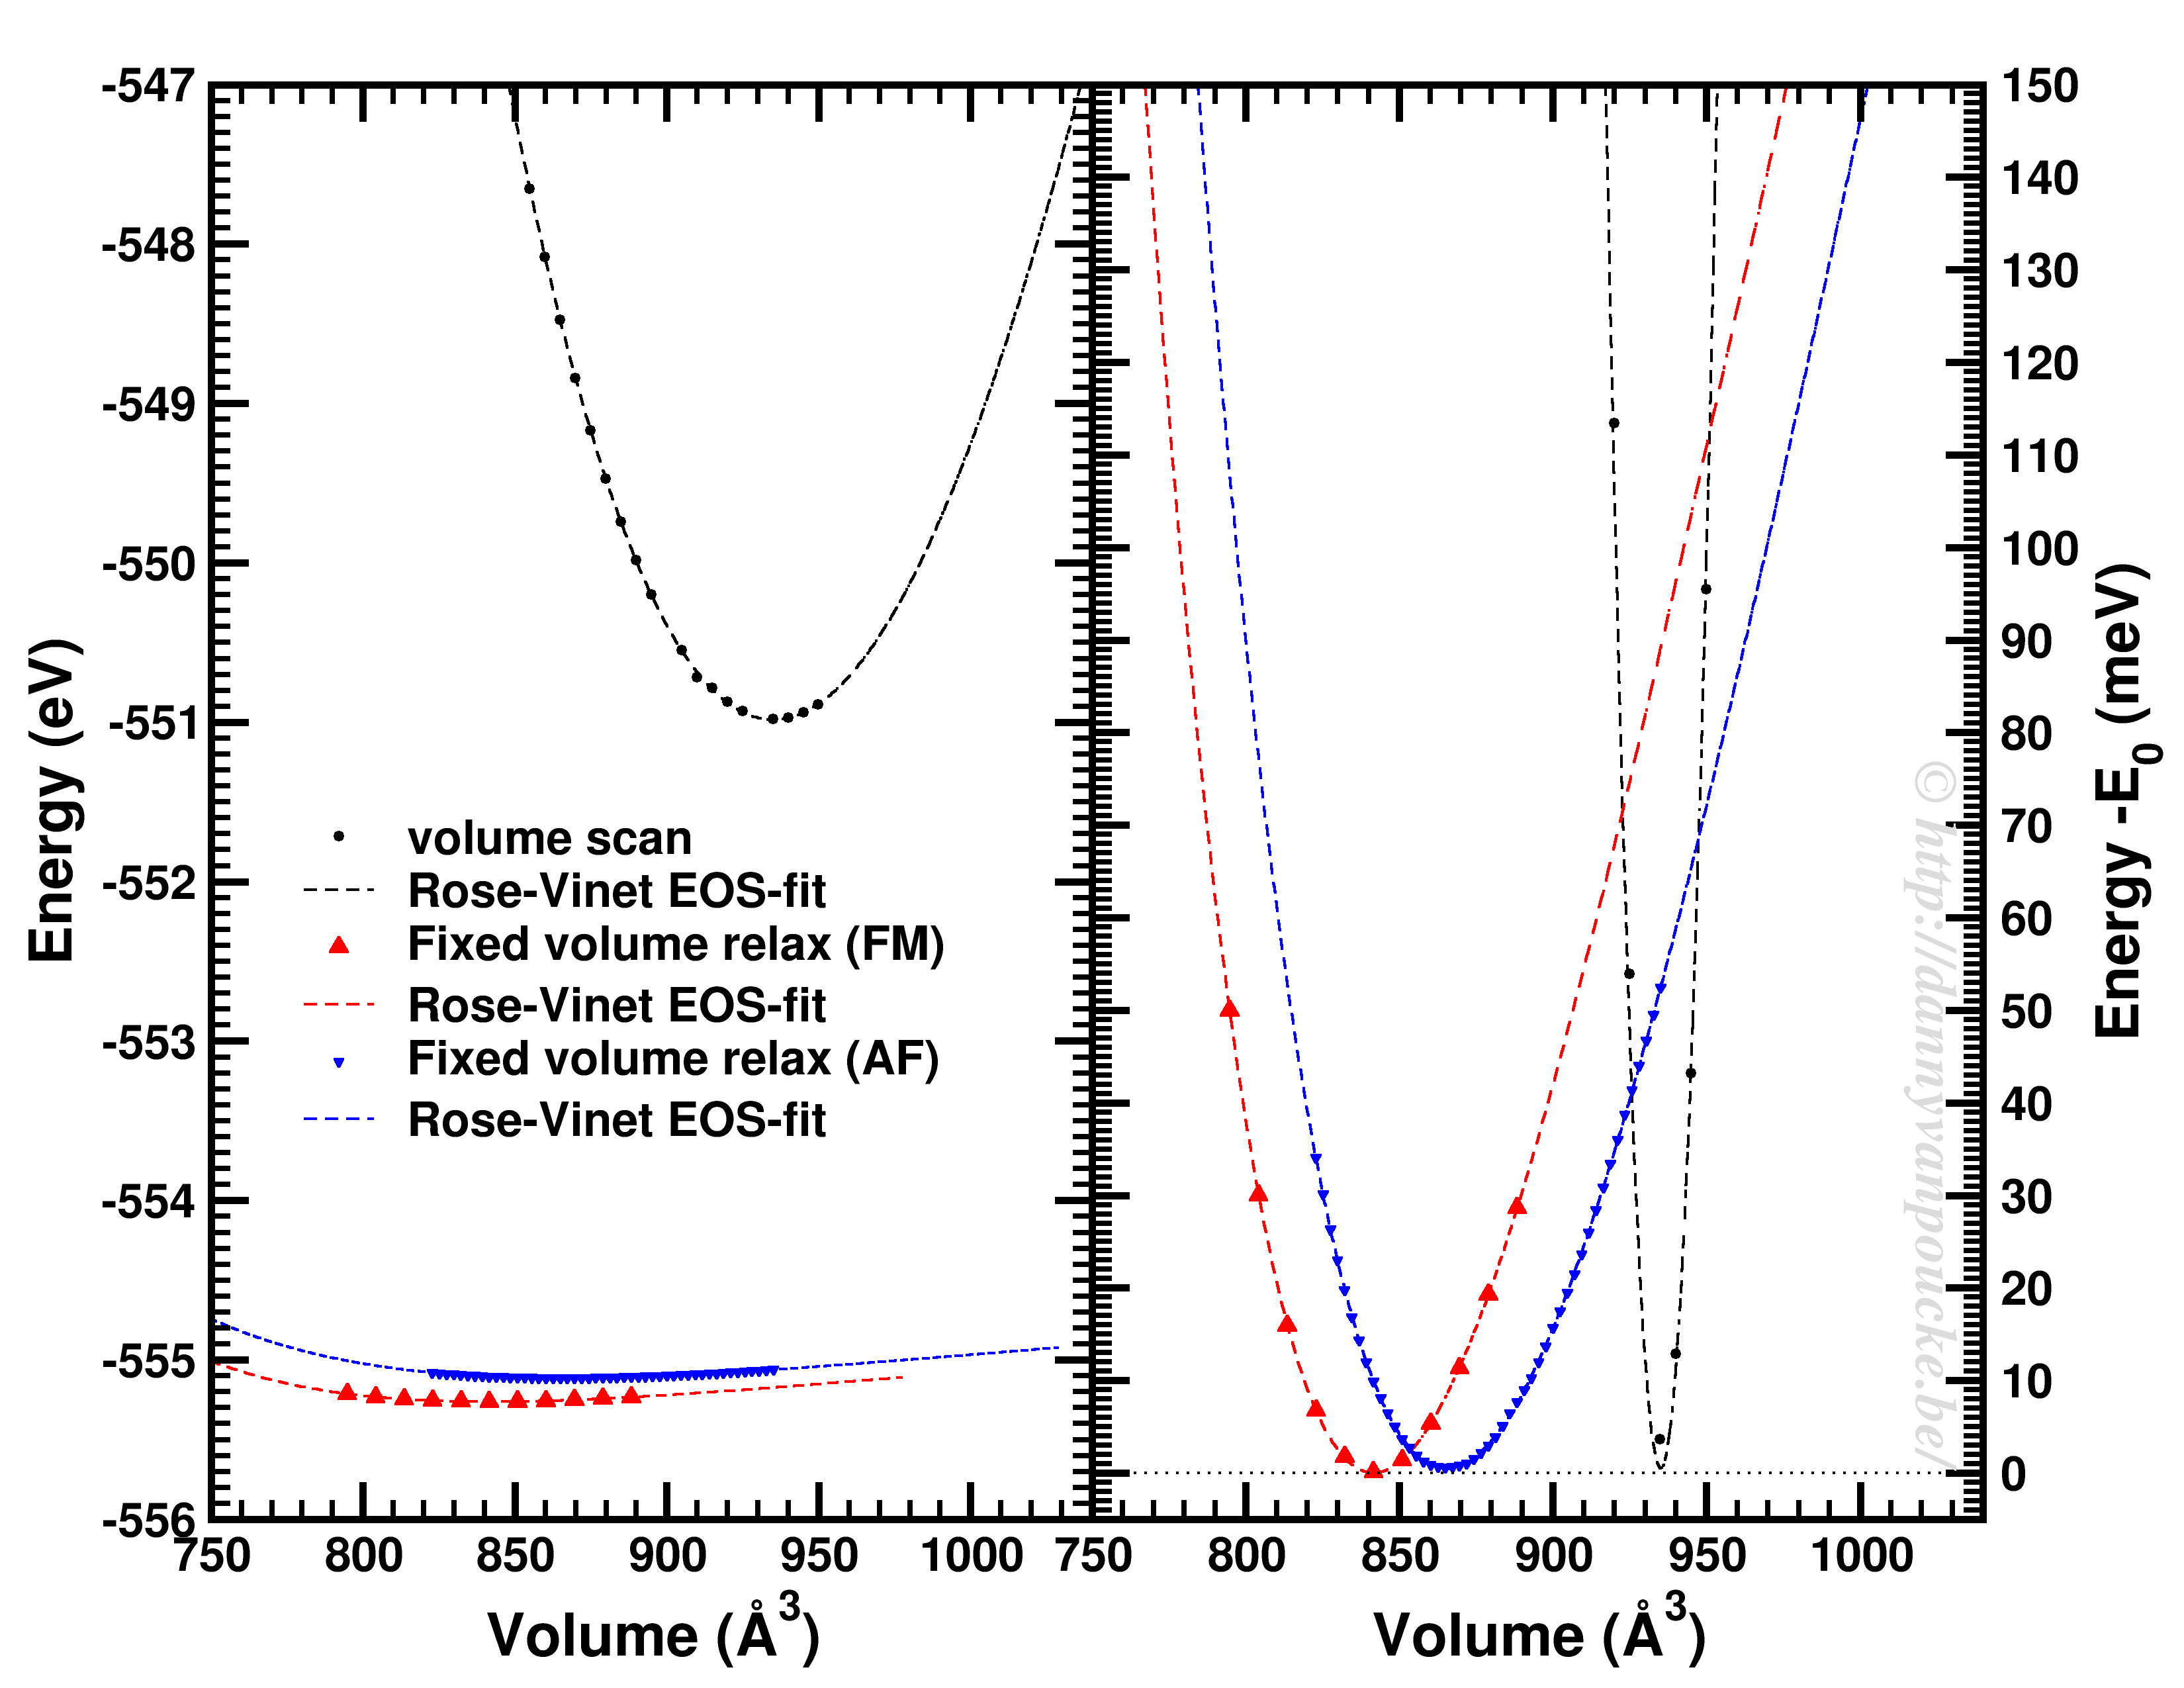
Comparison of a volume scan and an EOS-fit to fixed volume optimizations for a Metal-Organic Framework with MIL53/47 topology.

We just saw that for simple systems, the simple volume scan can already be too simple. For more complex systems like MOFs, similar problems can be seen. The simple volume scan, as for graphite gives a too sharp potential (with a very large bulk modulus). In addition, internal reordering of the atoms gives rise to very large changes in the energy, and the equilibrium volume can move quite a lot. It even depends on the spin-configuration.

In conclusion: the safest way to get a good equilibrium volume is unfortunately also the most expensive way. By means of an equation of state fit to a set of fixed volume structure optimizations the ground state (experimental) equilibrium volume can be found. As a bonus, the bulk modulus is obtained as well.

Permanent link to this article: https://dannyvanpoucke.be/vasp-tutor-eosfit-en/

Review of 2016

2016 has come and gone. 2017 eagerly awaits getting acquainted. But first we look back one last time, trying to turn this into a tradition. What have I done during the last year of some academic merit.

Publications: +4

Completed refereeing tasks: +5

  • ACS Sustainable Chemistry & Engineering
  • The Journal of Physical Chemistry
  • Journal of Physics: Condensed Matter (2x)
  • Diamond and Related Materials

Conferences: +4 (Attended) & + 1 (Organized)

PhD-students: +2

  • Arthur De Vos : (Jan.-Mar., Ghent University, Ghent, Belgium )
  • Mohammadreza Hosseini (okt.-… ,Phd student physical chemistry, Tarbiat Modares University, Teheran, Iran)

Current size of HIVE:

  • 47K lines of program (code: 70 %)
  • 70 files
  • 44 (command line) options

Hive-STM program:

And now, upward and onward, a new year, a fresh start.

Permanent link to this article: https://dannyvanpoucke.be/review-of-2016-en/